Part X · Other kinds of models
Ch 39. Seeing pictures
Pictures as tokens
A transformer doesn’t care what its tokens stand for; it just needs a row of vectors (Ch 5). A picture can become one by being cut into square patches, each turned into a vector, just like a token. This is the vision transformer.[1]
A transformer doesn’t care what its tokens stand for. All it needs is a row of vectors (Ch 5). Text becomes that row by splitting into tokens. A picture can do the same by being cut into square patches, each turned into a vector by multiplying its pixel values by learned weights, plus a position, just like a token. The rest is the familiar stack of blocks. This is the vision transformer.[1][1]
Here it is with CLIP ViT-B/32, a real model, on simple pictures drawn for this page. It cuts each 224×224-pixel picture into a 7×7 grid of 32×32-pixel patches: 49 “tokens”. Pick a patch:
Cut a picture into tokens
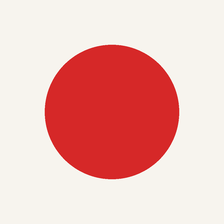
The patches in reading order, like a sentence of tokens
- Patch 1
- Patch 2
- Patch 3
- Patch 4
- Patch 5
- Patch 6
- Patch 7
- Patch 8
- Patch 9
- Patch 10
- Patch 11
- Patch 12
- Patch 13
- Patch 14
- Patch 15
- Patch 16
- Patch 17
- Patch 18
- Patch 19
- Patch 20
- Patch 21
- Patch 22
- Patch 23
- Patch 24
- Patch 25
- Patch 26
- Patch 27
- Patch 28
- Patch 29
- Patch 30
- Patch 31
- Patch 32
- Patch 33
- Patch 34
- Patch 35
- Patch 36
- Patch 37
- Patch 38
- Patch 39
- Patch 40
- Patch 41
- Patch 42
- Patch 43
- Patch 44
- Patch 45
- Patch 46
- Patch 47
- Patch 48
- Patch 49
Patch 25 as a vector
Each 32×32-pixel patch becomes a vector of 768 numbers (the first 32 shown). This patch looks exactly like 4 others, so they all get the same vector.
Notice that patches of plain background all turn into the same vector, the way the same word always starts as the same embedding.
A patch, in numbers
Each 32×32 patch has 3 colors per pixel: 32 × 32 × 3 = 3,072 numbers. One learned 3,072 × 768 weight matrix turns it into 768 numbers, the same matrix for every patch, and a position vector is added. One extra learned vector goes at the front, a class token, so the transformer reads 50 vectors, and at the end the class token’s vector stands for the whole picture.[1] CLIP then maps that vector, and the text side’s summary of a caption, into a shared space of 512 numbers.
A shared map for words and pictures
CLIP was trained on 400 million pictures with their captions from the internet, learning to put each picture close to its own caption.[2] So words and pictures land in one shared space. Pick some words and see which pictures land closest:
CLIP was trained on 400 million pictures paired with their captions from the internet. It has two parts, one that reads pictures and one that reads text, and training pushed each picture’s vector close to its own caption’s vector and away from the others.[2][2] The result is a single space where words and pictures can be compared. Pick some words and see which pictures land closest:
Match words to pictures
- 42% 0.27
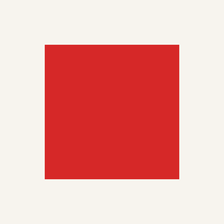 32% 0.27
 15% 0.26
 3.1% 0.24
 3.0% 0.24
 2.2% 0.24
 0.9% 0.23
 0.6% 0.23
 0.4% 0.22
 0.3% 0.22
 0.1% 0.21
 0.1% 0.21
The percentages share 100% among these 12 pictures. The small number under each is the similarity of the two vectors, from −1 to 1. CLIP's similarities sit in a narrow band, so small differences decide the match. When nothing fits, like “a photo of a cat”, the percentages still add up to 100%, but even the best similarity is lower than for any of the exact descriptions.
Type your own words and CLIP's text half, running live, matches them to the pictures. Choose a model tier to run a real model in your browser.
For each of the 12 exact descriptions, the right picture comes first. Vaguer words are harder: “something round” barely prefers a circle.
Comparing a caption with pictures
For each caption, CLIP takes the cosine similarity with each picture’s vector and multiplies by a learned temperature, 100 for this model, before the softmax. The similarities themselves sit close together: “a red circle” scores 0.271 with the red circle and 0.268 with the red square. Multiplied by 100, that 0.003 gap gives the circle 42% and the square 32%. In training, each batch held 32,768 picture–caption pairs: every picture had to pick out its own caption from all 32,768, and every caption its picture.[2]
Chat models that see
A multimodalmultimodal model: A model that takes in more than one kind of input, such as text and pictures. Ch 39 chat model combines the two ideas: a vision model turns the picture into vectors, and the language model reads them alongside your words.[3] To the language model, the picture is just more tokens.
A multimodalmultimodal model: A model that takes in more than one kind of input, such as text and pictures. Ch 39 chat model puts the two ideas together. A vision model like CLIP’s turns the picture into patch vectors, a small layer converts those into the same kind of vectors as text tokens, and the language model reads them in its context alongside your words.[3][3] To the language model, the picture is just more tokens.
Agents that use a screen
Put a model that sees inside the loop from Ch 29 and you get a computer-use agentcomputer-use agent: An agent that sees screenshots and acts by clicking and typing, so it can work programs the way a person does. Ch 39. The harness takes a screenshot and gives it to the model with the task. The model answers with an action, like a click at a spot on the screen or some text to type. The harness does it, takes a new screenshot, and goes round again, as in this made-up run:
screenshot 1 → click(412, 230)
screenshot 2 → type("cat rhymes")
screenshot 3 → key("Enter")
screenshot 4 → done
It’s hard. To click a button, the model has to work out where it is in pixels, which Anthropic had to train its model to do.[4] On a test of 369 real computer tasks, people finished about 72% and the best model 12%.[5] And everything on the screen reaches the model, so a web page can hide instructions in it, as in Ch 34.[4]
Put a model that sees inside the loop from Ch 29 and you get a computer-use agentcomputer-use agent: An agent that sees screenshots and acts by clicking and typing, so it can work programs the way a person does. Ch 39, which works any program the way a person does. The harness takes a screenshot and gives it to the model with the task. The model answers with a tool call for an action: move the pointer and click at a position, type text, press a key. The harness carries it out, and the next screenshot is the tool’s result. This run is made up:
screenshot 1 → click(412, 230)
screenshot 2 → type("cat rhymes")
screenshot 3 → key("Enter")
screenshot 4 → done
The hard part is pointing. To click a button, the model has to give its position in pixels, and Anthropic had to train its model to count pixels across the screen, a skill it compares to counting the letters in a word (Ch 16). Seeing the screen as a series of screenshots, like a flipbook, the model can also miss a message that appears and vanishes between them.[4][4]
OSWorld tests this on 369 tasks in real desktop and web apps, each checked by a script that inspects the computer afterwards. People finished over 72% of them and the best model of early 2024 about 12%, failing mostly at finding the right place on the screen and at knowing how the apps work.[5][5] Later that year Anthropic reported 14.9% for its first computer-use model.[4][4] And everything on the screen reaches the model, so a web page can carry instructions just as the poisoned page in Ch 34 did; Anthropic names this prompt injection as a main risk of computer use.[4][4]
What a screenshot costs
Anthropic’s models read a picture in 28 × 28-pixel patches, one token each, so a screenshot costs tokens.[6] A 1280 × 800 screen is 46 × 29 = 1,334 tokens, against the 49 patches of CLIP’s 224-pixel pictures above. Every step adds one, and each call re-reads them all, as in Ch 29: after ten steps, a harness that keeps every screenshot sends 13,340 tokens of them with each call.
Recipe card
Recap
- A vision transformer cuts a picture into patches and treats each patch like a token.
- CLIP puts pictures and captions into one shared space, so words can find matching pictures.
- Chat models that see turn a picture into tokens and put them in the context next to the text.
- A computer-use agent is the agent loop with screenshots as tool results and clicks and typing as actions. Pointing at the right pixel is hard, and anything on the screen can carry an injected instruction.
- A patch’s 3,072 pixel values become 768 numbers; CLIP scales its similarities by 100 before the softmax.
Next question: these models read pictures. How do image generators make them?
Sources
- Alexey Dosovitskiy et al. (2021). An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. ICLR 2021.
- Alec Radford et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. ICML 2021.
- Haotian Liu et al. (2023). Visual Instruction Tuning. NeurIPS 2023.
- Anthropic (2024). Developing a computer use model. Anthropic. Accessed October 25, 2026.
- Tianbao Xie et al. (2024). OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. arXiv.
Sources
- Alexey Dosovitskiy et al. (2021). An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. ICLR 2021.
- Alec Radford et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. ICML 2021.
- Haotian Liu et al. (2023). Visual Instruction Tuning. NeurIPS 2023.
- Anthropic (2024). Developing a computer use model. Anthropic. Accessed October 25, 2026.
- Tianbao Xie et al. (2024). OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. arXiv.
Sources
- Alexey Dosovitskiy et al. (2021). An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. ICLR 2021.
- Alec Radford et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. ICML 2021.
- Haotian Liu et al. (2023). Visual Instruction Tuning. NeurIPS 2023.
- Anthropic (2024). Developing a computer use model. Anthropic. Accessed October 25, 2026.
- Tianbao Xie et al. (2024). OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. arXiv.
- Anthropic (2026). Vision. Claude API documentation. Accessed October 25, 2026.